Watermark Models vs Rephrase Models
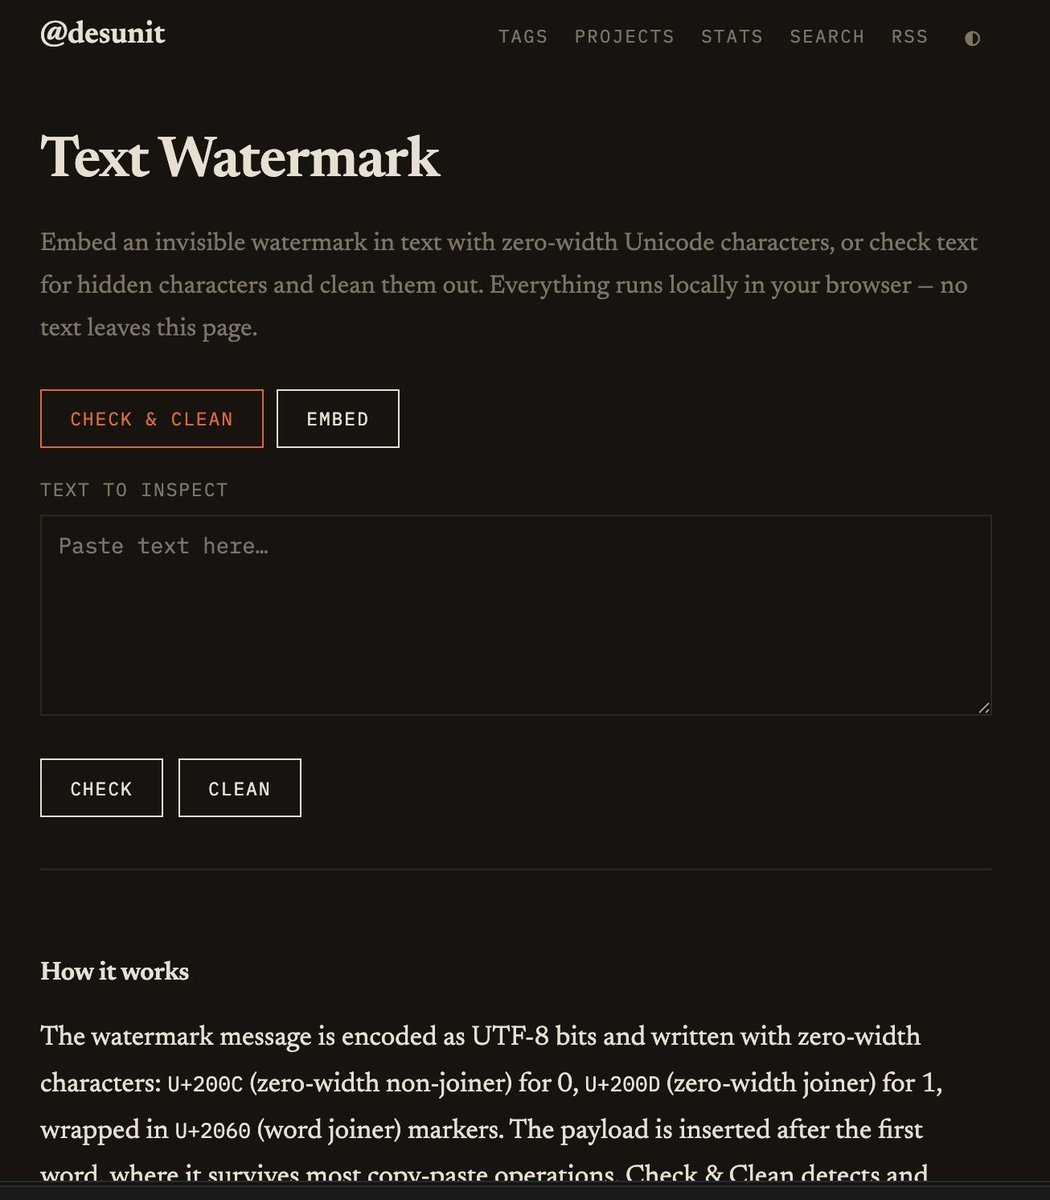
As you all know, Anthropic is going to watermark text, and of course that sparked a lot of thinking about how it could be done. One idea that immediately came to me was to hide the text using Unicode. I quickly built a prototype (see the link below), but later realized it’s probably too easy -though it might survive Copy & Paste, it’s really just a first layer. The second layer would be statistical or sampling-based watermarks, which I think could be solved with rephrasing.
I can see more and more startups getting into this, and building their own "rephrase" models that can be fine-tuned to match the company’s/user's voice.
We'll end up with watermark models fighting watermark-removal models and every generation of one creating training data for the other.
the tool: desunit.com/blog/projects/…
Archive
2026
- 30 Sept 2026 Exercise as a system-wide software update for your body𝕏
- 28 Sept 2026 Agency Is the Most Valuable Employee Trait𝕏
- 25 Sept 2026 Why paper-filtered coffee may be better for cholesterol𝕏
- 23 Sept 2026 50 Mental Models Sorted by Popularity𝕏
- 21 Sept 2026 DeepSeek V4.1 Flash Hacked 11 of 11 Targets for $5𝕏
- 18 Sept 2026 OpenAI Moves Closer to Lawyers with Astra for Law𝕏
- 17 Sept 2026 Why reading to kids strengthens bonds and brain development𝕏
- 14 Sept 2026 How AI Is Changing Conway’s Law in Internal Software𝕏
- 11 Sept 2026 HIIT before stress may blunt the cortisol response𝕏
- 9 Sept 2026 OpenAI, Navier-Stokes, and the cost of huge AI agent swarms𝕏
- 7 Sept 2026 Google AI Mode favors trust over the cheapest price𝕏
- 5 Sept 2026 Optimizing for Different Risk Levels in Automation𝕏
- 2 Sept 2026 Why journaling reveals patterns you can’t see yourself𝕏
- 31 Aug 2026 Skipping breakfast, depression risk, and the HALT check𝕏
- 28 Aug 2026 Why meaning in life matters more than searching for it𝕏
- 26 Aug 2026 Why Short Videos Make It Hard to Stop Scrolling𝕏
- 24 Aug 2026 Lessons from Les Misérables for better business positioning𝕏
- 23 Aug 2026 A week using my custom social post tool𝕏
- 21 Aug 2026 Why Charging From Day One Reveals Real User Demand𝕏
- 19 Aug 2026 Watermark Models vs Rephrase Models𝕏
- 19 Aug 2026 Building a custom social tool with Next.js and SQLite𝕏
- 14 Aug 2026 Why a 7,000-Step Walk Can Help Mental Health𝕏
- 11 Aug 2026 Why AI Companies Will Have Fewer Managers and More Agents𝕏
- 5 Aug 2026 How AI Changes Shape Up and the Cool-Down Week𝕏
- 3 Aug 2026 Donald Hoffman on perception, consciousness, and reality𝕏
- 31 Jul 2026 Robust principles for small startups in a big world𝕏
- 29 Jul 2026 SEO Traffic Is Shrinking as AI Answers Change Search𝕏
- 29 Jul 2026 Selection bias in TrustMRR revenue data𝕏
- 27 Jul 2026 The 12-Factor Company in the AI Era𝕏
- 24 Jul 2026 AI Agents Will Become the Primary Users of Software𝕏
- 24 Jul 2026 Ask for ratings at the right moment𝕏
- 22 Jul 2026 Why I think we’re closer to the singularity than ever𝕏
- 20 Jul 2026 Building an iterative AI skill that learns across MCPs𝕏
- 20 Jul 2026 Expanding my MCP toolbelt with Google Play analytics𝕏
- 17 Jul 2026 Built a subscription system with Google Play and App Store𝕏
- 17 Jul 2026 Chinese AI models just overtook Claude in frontend coding𝕏
- 15 Jul 2026 Self-Compassion Beats the Inner Critic𝕏
- 10 Jul 2026 China’s rapid rise in space and global power𝕏
- 8 Jul 2026 Why virtual desktops are a game changer for multitasking𝕏
- 3 Jul 2026 Why Tech and Non-Tech People See AI So Differently𝕏
- 24 Jun 2026 Shut The Noise Off𝕏
- 12 Jun 2026 Why your content should live on your own site𝕏
- 8 Jun 2026 Built an MCP server for Reddit Ads API v3𝕏
- 7 Jun 2026 Why users don’t trust new apps: abandonment concerns𝕏
- 3 Jun 2026 AI Shipping Faster Than Learning: The Startup Trap𝕏
- 1 Jun 2026 Built an MCP server for Appfigures to track app performance𝕏
- 1 Jun 2026 The Verge Says WeWork Was a Joke Until SpaceX Filing𝕏
- 30 May 2026 Verge vs Elon Musk: Why SpaceX Isn’t a Meme Stock𝕏
- 30 May 2026 Journal + LLMs: Spot Patterns in Your Thinking Habits𝕏
- 30 May 2026 KidTeller AI Story Breakthrough From One Prompt𝕏
- 29 May 2026 Legacy code risk: the handover tax and key-person RISK𝕏
- 25 May 2026 How Repetition Shapes Learning From Hippocampus to Cortex𝕏
- 24 May 2026 How AI Coding Changed My MVP Build Process This Year𝕏
- 23 May 2026 Why Faster Project Updates Enable More SaaS and Apps𝕏
- 21 May 2026 Composer 2.5 tops CursorBench at 20x lower cost than Opus𝕏
- 20 May 2026 Procrastination Disguised as Research: Ship Decisions Faster𝕏
- 18 May 2026 China Deploys Medical AI at Scale in Real Hospitals𝕏
- 15 May 2026 How Losing a Senior Engineer Exposes Hidden System Knowledge𝕏
- 13 May 2026 Google Cloud growth outpaces AWS and Azure in AI race𝕏
- 11 May 2026 OpenAI GPT Goblins: How AI Behavioral Artifacts Scale𝕏
- 8 May 2026 Mozilla Used Claude to Find 271 Firefox Vulnerabilities𝕏
- 6 May 2026 The LLM Fallacy: AI Output Can Distort Self-Perception𝕏
- 1 May 2026 Make Your Future Self Feel Real to Stop Procrastinating𝕏
- 29 Apr 2026 Do We Know What Consciousness Is or If AI Can Be It𝕏
- 27 Apr 2026 Recursive Language Models: Why Bigger Context Can Hurt AI𝕏
- 24 Apr 2026 Anterior Mid-Cingulate Cortex: Discipline as Brain Training𝕏
- 22 Apr 2026 Why Learning Needs Friction in a Screen-Heavy World𝕏
- 20 Apr 2026 Reading as a Silence Problem: Focus, Time, and Advantage𝕏
- 17 Apr 2026 Automata vs Humans: Why 24/7 Consistency Wins𝕏
- 15 Apr 2026 AI-Driven Layoffs: Demand Shock and Automation Tax Debate𝕏
- 13 Apr 2026 Most AI adoption fails: executives trust, workers ignore𝕏
- 10 Apr 2026 AI Zen Sickness: When AI Outthinks Your Ego𝕏
- 8 Apr 2026 You Don’t Need a Co-Founder: Equity, Hiring, and AI𝕏
- 6 Apr 2026 How Liquid Death Uses Humor to Build a Brand Moat𝕏
- 3 Apr 2026 AI Replaces Managers: A New Coordination Layer𝕏
- 1 Apr 2026 Beginner Mindset and Tiny Docs for AI Engineering𝕏
- 30 Mar 2026 Why Jira Isn’t Enough: Shared Context Beats Tickets𝕏
- 27 Mar 2026 Dev Browser Cuts Turns and Tokens for Faster AI Coding𝕏
- 25 Mar 2026 Bezos’ $100B AI Plan to Upgrade Factories and Manufacturing𝕏
- 23 Mar 2026 AI Remixing Live: How Models Distill and Route Calls𝕏
- 20 Mar 2026 AI Will Concentrate Value Through Distribution, Not Fragment Markets𝕏
- 18 Mar 2026 Could This Be the Last Job? AI, Identity, and Anxiety𝕏
- 16 Mar 2026 Fruit Flies as Model Organisms: Virtual Fly Brain Loop𝕏
- 13 Mar 2026 AI chatbots and delusions: confirmation bias spiral𝕏
- 11 Mar 2026 Why “Goals” Fail: Use Few, Clear, Owned Priorities𝕏
- 9 Mar 2026 AI founders fear startups becoming features𝕏
- 6 Mar 2026 AI Era Startup Defensibility: Features Get Cloned𝕏
- 4 Mar 2026 AI reasoning models show System 1 vs System 2 collapse𝕏
- 2 Mar 2026 Startups Now “Wrap” APIs: The Shift from Building to Composing𝕏
- 27 Feb 2026 Why Tests and Docs Are the New Moat𝕏
- 25 Feb 2026 GIFs, Photos, and 10,000-Year Storage Thanks to Microsoft𝕏
- 23 Feb 2026 ADHD Traits as a Creative Advantage, Not a Deficit𝕏
- 20 Feb 2026 Taste Is the New Core Skill in the Age of AI𝕏
- 18 Feb 2026 Zhiyuan Robotics Expedition A3: Humanoid Robot Scale Up𝕏
- 16 Feb 2026 LLMs as amplifiers: how experts verify science in 12 hours𝕏
- 13 Feb 2026 LLM “Thinking” Explained: More Compute, Chain-of-Thought Limits𝕏
- 11 Feb 2026 AI Gets 50–60% on New Research Math Benchmarks𝕏
- 9 Feb 2026 Humanoid robots: China dominates with the EV-style playbook𝕏
- 6 Feb 2026 How LLMs Kill the Workflow Interface Moat𝕏
- 4 Feb 2026 Built a custom CRM for my wife in two days𝕏
- 2 Feb 2026 LLMs Make Code Cheap: Clarity and Accountability Win𝕏
- 30 Jan 2026 AI Makes Junior Dev Work Faster but Raises the Bar𝕏
- 28 Jan 2026 Why I Love Claude More Than the Marketing Hype𝕏
- 26 Jan 2026 AI Index 2025: efficiency drives progress and global shift𝕏
- 24 Jan 2026 Cursor Fixed ChordIQ and Migrated Apps After Google Takedown𝕏
- 23 Jan 2026 Fix this gene𝕏
- 21 Jan 2026 Space Race 2.0: China Plans Up to 200,000 Satellites𝕏
- 20 Jan 2026 Fear to Launch: KidTeller’s First Customer and Rapid Fixes𝕏
- 19 Jan 2026 AI Human Bottleneck: Orchestration Beats Execution𝕏
- 16 Jan 2026 Why teams win with AI: context is the real moat𝕏
- 14 Jan 2026 Stack Overflow’s AI push doubles revenue to $115M𝕏
- 13 Jan 2026 Choosing Curiosity Over Fear: Turn Ideas Into Projects𝕏
- 9 Jan 2026 Quantum computing and public-key encryption risks explained𝕏
- 9 Jan 2026 Why I Chose Curiosity Over Fear
- 9 Jan 2026 Marketing Mindset Shift for Developers: 1/10 Build, 9/10 Sell𝕏
- 7 Jan 2026 Solo founders are up in 2025, boosted by AI and speed𝕏
- 5 Jan 2026 2026: Org Process Determines Speed as AI Writes Code𝕏
- 4 Jan 2026 Stack Overflow Questions Drop as LLMs Take Over Coding𝕏
2025
- 31 Dec 2025 How Josh Woodward Helped Google Maintain Dominance𝕏
- 29 Dec 2025 Token-Efficient Vibe Coding: Metrics for LLM Developer Work𝕏
- 28 Dec 2025 Real AI Progress Starts With Curiosity, Not Mandates𝕏
- 26 Dec 2025 AI Visual Editing and the Split Between Programming and Coding𝕏
- 24 Dec 2025 ASML Engineers, EUV Chipmaking, and China’s Progress Timeline𝕏
- 24 Dec 2025 KidTeller Feedback Loop to Product-Market Fit𝕏
- 22 Dec 2025 OpenAI Cash Burn and Why Gemini or China Could Win𝕏
- 21 Dec 2025 AI Coding 2025 Report Finds 76% Jump in Code Output𝕏
- 19 Dec 2025 KidTeller usability update adds character preview and first page𝕏
- 17 Dec 2025 Google Puts AI in Orbit as Starcloud Runs Gemma in Space𝕏
- 15 Dec 2025 YC’s Startup Success Questions: Determination Wins𝕏
- 14 Dec 2025 Musk and Bezos Race to Put AI Data Centers in Space𝕏
- 12 Dec 2025 What If AGI Never Happens: GPU Limits, Memory, Scaling Costs𝕏
- 10 Dec 2025 Vercel cut 9 SDRs to 1 with AI QA agent in 6 weeks𝕏
- 8 Dec 2025 From Chatbots to AI Agents: OpenRouter’s Agentic Shift𝕏
- 7 Dec 2025 Transparent Leadership: The Router Model for Building Teams𝕏
- 6 Dec 2025 Trying Antigravity: Gemini 3 demand vs Claude speed𝕏
- 3 Dec 2025 Technical Deflation: Why Projects May Never Start𝕏
- 1 Dec 2025 AI “Vibe-Coded” SaaS Wipes a Team, Leaves Legal Risks𝕏
- 30 Nov 2025 Charlie Munger Lessons on Curiosity, Risk, and Long-Term Thinking𝕏
- 28 Nov 2025 MIT Study Finds AI Could Replace 11.7% of US Workforce𝕏
- 27 Nov 2025 AI agents are making experienced builders far more productive𝕏
- 24 Nov 2025 Inside Cursor's Culture, Hiring, and Product Bar𝕏
- 23 Nov 2025 AI-generated songs on Spotify are growing fast𝕏
- 19 Nov 2025 KidTeller launches on Product Hunt with personalized kids stories𝕏
- 17 Nov 2025 Chat Control Returns With Mass Message Scanning𝕏
- 16 Nov 2025 The Complete Guide to Stoicism Felt Strangely Familiar𝕏
- 14 Nov 2025 How LLMs Separate Memorization from Reasoning𝕏
- 12 Nov 2025 Architectural debt starts outside the code𝕏
- 10 Nov 2025 KidTeller: Personalized Storybooks for Kids𝕏
- 9 Nov 2025 The platypus is venomous and its sting is brutal𝕏
- 7 Nov 2025 Chinese Open-Source Models Are Surging Ahead𝕏
- 7 Nov 2025 Book: The Complete Guide to Stoicism
- 5 Nov 2025 AI video tools may flood social feeds with spam𝕏
- 3 Nov 2025 Why busyness became a religion𝕏
- 2 Nov 2025 Human Creativity Meets AI in a Short Film𝕏
- 31 Oct 2025 Hidden value systems in AI models reveal surprising biases𝕏
- 27 Oct 2025 Artificial cognitive selection and the future of embryo IQ testing𝕏
- 26 Oct 2025 Anathem and the problem of good crap𝕏
- 20 Oct 2025 Rude prompts may improve LLM accuracy𝕏
- 17 Oct 2025 Why great writing feels alive and AI writing feels flat𝕏
- 15 Oct 2025 AI Agents Replace B Players, Not A Players𝕏
- 13 Oct 2025 Ahrefs SEO Competitor Analysis Tips for Reverse Engineering𝕏
- 12 Oct 2025 Wandering Is Not Procrastination𝕏
- 12 Oct 2025 Why Writing Thoughts Down Helps Your Brain Relax𝕏
- 10 Oct 2025 Using ChatGPT for Competitive Analysis in News SEO𝕏
- 8 Oct 2025 a16z Enterprise on the AI-native apps startups are buying𝕏
- 7 Oct 2025 Why developers should understand how things work conceptually𝕏
- 7 Oct 2025 Why candidates should complete a simple coding task first𝕏
- 6 Oct 2025 SIM cards are tiny microcontrollers𝕏
- 6 Oct 2025 Why China May Lead the Next AI Breakthrough𝕏
- 3 Oct 2025 Governments Push More Device-Level Content Scanning𝕏
- 1 Oct 2025 OpenAI Scores 12 of 12 at the 2025 ICPC World Finals𝕏
- 30 Sept 2025 Why ChatGPT is for rare bug fixes, not speed𝕏
- 29 Sept 2025 Google reports devs use AI for 2 hours a day𝕏
- 26 Sept 2025 How leverage amplifies results in the AI era𝕏
- 24 Sept 2025 Building a High-Performance Organization𝕏
- 24 Sept 2025 Nietzsche, walking, and the making of Thus Spoke Zarathustra𝕏
- 22 Sept 2025 OpenAI study shows how people use ChatGPT in 2025𝕏
- 19 Sept 2025 Google’s AP2 Lets AI Agents Complete Payments Securely𝕏
- 17 Sept 2025 AI Breakthroughs Keep Coming From New Data Sources𝕏
- 17 Sept 2025 Drinking Water During Meals Doesn’t Harm Digestion𝕏
- 17 Sept 2025 EU Chat Control Law Threatens Private Messaging𝕏
- 15 Sept 2025 Gen Z Is Using TikTok Search Nearly as Much as Google𝕏
- 14 Sept 2025 Goals vs aims and why identity matters𝕏
- 12 Sept 2025 OpenAI launches AI Academy with free ChatGPT courses𝕏
- 10 Sept 2025 The most ridiculous AI implementation fails𝕏
- 8 Sept 2025 Why Hybrid Agents May Beat Bigger Models𝕏
- 3 Sept 2025 Precognition and the possibility that time is not linear𝕏
- 1 Sept 2025 Sell the team, not just the tool𝕏
- 29 Aug 2025 Why a sharp economic downturn could hit within months𝕏
- 25 Aug 2025 AI abundance and the real challenge of sharing it𝕏
- 22 Aug 2025 ChatGPT referral traffic is shifting toward answer-first content𝕏
- 18 Aug 2025 The Region Beta Paradox and Why Mild Pain Delays Action𝕏
- 13 Aug 2025 Why AI Shouldn’t Replace Your Thinking𝕏
- 12 Aug 2025 In the long run, LLMs make us dumber
- 11 Aug 2025 Stanford Study Shows AI Boosts Simple Coding, Not Complex Systems𝕏
- 8 Aug 2025 AI Is Eating the Internet and Changing Content Distribution𝕏
- 6 Aug 2025 Money Creation, Credit, and Asset Bubbles Explained𝕏
- 4 Aug 2025 AI Gold Rush May Be Peaking as VC Money Floods In𝕏
- 1 Aug 2025 Why Great Engineers Step Away From the Keyboard𝕏
- 30 Jul 2025 Frustration over ChatGPT invoice emails for accounting𝕏
- 29 Jul 2025 Why solo builders obsess over tiny product details𝕏
- 28 Jul 2025 How AI Is Helping Design Better Physics Experiments𝕏
- 25 Jul 2025 AI summaries are changing how people search𝕏
- 20 Jul 2025 AI-first pods are rewriting traditional IT services𝕏
- 18 Jul 2025 Mars as a Plan B for Humanity𝕏
- 14 Jul 2025 How the smartest founders are winning in AI𝕏
- 13 Jul 2025 AI talent wars are all about keeping top researchers𝕏
- 11 Jul 2025 Isomorphic Labs is launching human trials of AI-designed drugs𝕏
- 8 Jul 2025 Road to AGI
- 7 Jul 2025 Tail Latency Might Matter More Than You Think𝕏
- 6 Jul 2025 AI talent war heats up as bubble fears grow𝕏
- 4 Jul 2025 Context Engineering Is Replacing Prompt Engineering𝕏
- 2 Jul 2025 Amazon’s Warehouse Robots Signal the Need to Keep Learning𝕏
- 30 Jun 2025 How AI models behave in Diplomacy𝕏
- 29 Jun 2025 Sukunaarchaeum: the microbe that behaves like a virus𝕏
- 27 Jun 2025 Why lines of code are a meaningless productivity metric𝕏
- 25 Jun 2025 How ChatGPT May Be Training Us to Think Less𝕏
- 23 Jun 2025 Publishers Face the Post-Search Era as AI Cuts Traffic𝕏
- 22 Jun 2025 AI Video Could Make Learning Stick for Kids𝕏
- 20 Jun 2025 Sam Altman on AGI, ChatGPT, and chaotic leadership𝕏
- 18 Jun 2025 Why GenAI coding tools help me but still need careful review𝕏
- 17 Jun 2025 Stripe’s early wall after wall and the API outage nobody noticed𝕏
- 15 Jun 2025 How AI Helped a Founder Fight a 2-Year Legal Nightmare𝕏
- 13 Jun 2025 Japanese Scientists Create Seawater-Melting Plastic𝕏
- 11 Jun 2025 Using AI in interviews reveals real engineering skill𝕏
- 9 Jun 2025 Sam Altman Teases a Rewrite of Intelligence𝕏
- 7 Jun 2025 Why the Right Co-Founder Matters for Solo Founders𝕏
- 7 Jun 2025 Why I chase chaos in my side projects
- 7 Jun 2025 Seven Years of Diary Writing and What It Helped Me Do𝕏
- 6 Jun 2025 Cursor 1.0 adds BugBot, Memories, and Jupyter support𝕏
- 4 Jun 2025 How a hawk learned to use traffic lights to hunt𝕏
- 2 Jun 2025 Helped Heard Hugged: Listening Before Solving𝕏
- 30 May 2025 Clinical Trial for Stem Cell Spinal Cord Repair𝕏
- 28 May 2025 NVIDIA’s B40 GPU and the China export-limit cat and mouse𝕏
- 25 May 2025 Why Europe Keeps Undervaluing Its Own Startups𝕏
- 23 May 2025 Google Gemini Diffusion could change how text is generated𝕏
- 19 May 2025 The real AI value is in apps people actually love𝕏
- 18 May 2025 English’s lexical gaps and a missing word called stupible𝕏
- 16 May 2025 How Stripe Uses AI for Fraud Detection𝕏
- 14 May 2025 Clothes Change Us and Shape How We Think𝕏
- 13 May 2025 Clothes Change Us
- 12 May 2025 Does Cursor Have a Defensible Moat𝕏
- 11 May 2025 The App Store Freedom Act Could Change Apple’s Grip𝕏
- 7 May 2025 AI Pretended to Be a Rape Survivor on Reddit𝕏
- 5 May 2025 A tiny updater bug that burned 2 petabytes𝕏
- 4 May 2025 Reading The 5 Types of Wealth and choosing life daily𝕏
- 2 May 2025 Why ChatGPT Can Sound Too Flattering𝕏
- 29 Apr 2025 Qwen3 looks promising with open-source models and long context𝕏
- 28 Apr 2025 Anthropic on Detecting Malicious Uses of Claude𝕏
- 27 Apr 2025 AI Is Changing the Dev Workflow, Not Replacing Devs𝕏
- 25 Apr 2025 You’re not burnt out – you’re just bored out
- 23 Apr 2025 Why We Speed Up Near the Finish Line𝕏
- 21 Apr 2025 Why acqui-hiring is rising in tech𝕏
- 20 Apr 2025 AI Adoption Is a UX Problem𝕏
- 18 Apr 2025 Jet Li, AI, and the Future of Human IP𝕏
- 16 Apr 2025 Why Chasing Revenue Too Early Can Hurt Startups𝕏
- 14 Apr 2025 3D Brain Cultures Reveal Neurons Can Change Roles𝕏
- 13 Apr 2025 Buffett on trade deficits and tariffs𝕏
- 11 Apr 2025 A nuanced look at how AI could fail𝕏
- 9 Apr 2025 Shopify’s AI memo signals a new company standard𝕏
- 7 Apr 2025 What Anthropic’s Deep Dive Reveals About Claude𝕏
- 6 Apr 2025 GPT-4.5 passes the Turing test in new study𝕏
- 4 Apr 2025 A Puzzle That Led Me to Think About AI and Problem-Solving𝕏
- 2 Apr 2025 AI lets people with paralysis speak again using brain signals𝕏
- 2 Apr 2025 If you always go northeast, where will you end up?
- 31 Mar 2025 AI Code Feels Like Extra Pipes, Not Refactoring𝕏
- 30 Mar 2025 What Baby Brain Studies Reveal About Early Memory𝕏
- 28 Mar 2025 The Software Engineering Identity Crisis in the AI Era𝕏
- 26 Mar 2025 Google Rethinks Search in Response to ChatGPT𝕏
- 24 Mar 2025 Why deep learning is less mysterious than it seems𝕏
- 23 Mar 2025 Overthinking Is Just Fear in Disguise𝕏
- 21 Mar 2025 Stamina Means Staying True to What Matters𝕏
- 17 Mar 2025 Amazon’s Weekly Business Review and smarter data-driven decisions𝕏
- 16 Mar 2025 Why Firing Fast Can Be a Business Cheat Code𝕏
- 10 Mar 2025 Melbourne startup CL1 builds a biological computer𝕏
- 9 Mar 2025 Building Meaning in Life: A Perspective Shift𝕏
- 7 Mar 2025 Sesame’s voice AI feels human and raises scam concerns𝕏
- 5 Mar 2025 DeepSeek Sets the Open-Source Standard for AI Infrastructure𝕏
- 4 Mar 2025 Entrepreneurship Is Solving Problems Wherever You Work𝕏
- 2 Mar 2025 Hidden messages in Unicode variation selectors𝕏
- 28 Feb 2025 Why I Wash Fruit Before Eating It𝕏
- 26 Feb 2025 AI’s Horseless Carriage Phase and What Comes Next𝕏
- 26 Feb 2025 Wash your fruits – you’ll thank me later
- 24 Feb 2025 Multitasking Is Making You Less Productive𝕏
- 23 Feb 2025 How Deep Work Became an Addictive Business Model𝕏
- 22 Feb 2025 They Hijacked Our Flow State
- 21 Feb 2025 AI models are nearing parity and the fight is moving to consumers𝕏
- 20 Feb 2025 Why a U.S. Stablecoin Could Arrive Soon𝕏
- 19 Feb 2025 AI Is Making Software Cheaper to Build𝕏
- 18 Feb 2025 The E-Myth on Comfort, Growth, and Working On Your Business𝕏
- 17 Feb 2025 Stablecoins Are Becoming Fintech Infrastructure𝕏
- 16 Feb 2025 Company Culture Is Trust, Not Perks𝕏
- 15 Feb 2025 From VC Gold Rush to Funding Drought𝕏
- 14 Feb 2025 NOLIMA Shows LLMs Struggle With Long Context Reasoning𝕏
- 13 Feb 2025 Why quitting your job for startup life is not total freedom𝕏
- 13 Feb 2025 Anthropic's AI workforce index shows augmentation over replacement𝕏
- 13 Feb 2025 AI Changes How We Learn to Code𝕏
- 12 Feb 2025 How China’s Tech-Industrial Ecosystems Reinforce Growth𝕏
- 11 Feb 2025 Gemini 2.0 Flash for cost-effective large-scale PDF parsing𝕏
- 10 Feb 2025 Understanding reasoning LLMs and the four paths to better AI𝕏
- 9 Feb 2025 AI Startups Are Driving Series A Funding and Valuations𝕏
- 7 Feb 2025 Why IQ Is a Misleading Benchmark for AI𝕏
- 7 Feb 2025 Mentorship, Mastery, and AI: The Real Way to Learn Code
- 6 Feb 2025 SEO Is Shifting as AI Search Changes Discovery𝕏
- 5 Feb 2025 Why Genius Doesn’t End After 30𝕏
- 4 Feb 2025 Grayscale mode may help you spend less time on your phone𝕏
- 3 Feb 2025 Customers Don’t Care About AI-Powered Branding𝕏
- 2 Feb 2025 How AI Changes Creativity and What Makes Us Human𝕏
- 1 Feb 2025 How irritation in others can reveal our own blind spots𝕏
- 31 Jan 2025 DeepSeek Is Changing AI Model Distillation𝕏
- 30 Jan 2025 DeepSeek launches Janus-Pro open-source multimodal AI model𝕏
- 29 Jan 2025 Asimov on creativity and making unexpected connections𝕏
- 29 Jan 2025 How I Use Obsidian for Journaling and Reading Notes𝕏
- 28 Jan 2025 Patience Is Built on Trust and Safety𝕏
- 28 Jan 2025 Marshmallow Test and Parenting
- 27 Jan 2025 A Young Child's Appetite and Rapid Development𝕏
- 23 Jan 2025 AI tools are making programming easier than ever𝕏
- 22 Jan 2025 Instagram courts TikTok creators with cash bonuses and longer Reels𝕏
- 22 Jan 2025 France’s window tax and its unintended consequences𝕏
- 21 Jan 2025 AI Won't Replace You, But Users Will Pull Ahead𝕏
- 20 Jan 2025 Writing a blog post about sugar streaks and avoiding cake𝕏
- 20 Jan 2025 Why avoiding sugar is harder than intermittent fasting𝕏
- 20 Jan 2025 Why Non-Technical Founders Are Thriving in 2025𝕏
- 19 Jan 2025 How William Shockley’s Ego Helped Create Silicon Valley𝕏
- 18 Jan 2025 Put the Phone Down and Meet Kids at Eye Level𝕏
- 17 Jan 2025 People Care About Outcomes, Not Features𝕏
- 16 Jan 2025 ChatGPT scheduled tasks feel like Alexa on steroids𝕏
- 15 Jan 2025 Thoughts and missions need regular review𝕏
- 15 Jan 2025 Google’s Search Share Drops Below 90% as I Use LLMs More𝕏
- 14 Jan 2025 Learning Can Be an Excuse for Staying Stuck𝕏
- 14 Jan 2025 Why US debt fears miss how money is created𝕏
- 14 Jan 2025 EU Lacks a 100B Company Built From Scratch in 50 Years𝕏
- 13 Jan 2025 Europe’s innovation slowdown and the 50-year startup gap𝕏
- 13 Jan 2025 The Paradox of Loneliness and Learning to Be Alone𝕏
- 12 Jan 2025 Robotaxi drama and a first-date excuse𝕏
- 12 Jan 2025 Why I Stopped Drinking Alcohol and Stopped Caring𝕏
- 10 Jan 2025 StackOverflow’s decline feels hard to ignore𝕏
- 10 Jan 2025 Productivity Is About Outcomes, Not Busywork𝕏
- 9 Jan 2025 Parenting Means Letting Go of Control𝕏
- 8 Jan 2025 The 1% Rule Behind Big Wins𝕏
- 7 Jan 2025 Leadership Means Hiring Smarter People and Avoiding Micromanagement𝕏
- 6 Jan 2025 A year of LLM milestones, trends, and surprises𝕏
- 6 Jan 2025 Writing Down Completed Tasks Feels as Good as Checking Them Off𝕏
- 3 Jan 2025 LLMs Are Great for Fixing Bugs and Simplifying Code𝕏
- 2 Jan 2025 Sequential thinking may come from ancient navigation circuits𝕏
2024
- 31 Dec 2024 AI and the risk of deeper inequality𝕏
- 30 Dec 2024 How AI data centers are stressing the power grid𝕏
- 30 Dec 2024 Playing Digital Janitor While Sparking Innovation𝕏
- 25 Dec 2024 How AI Hallucinations Are Driving Scientific Breakthroughs𝕏
- 24 Dec 2024 Why Entrepreneurs Fail
- 24 Dec 2024 Cancer risk drops after 80 thanks to NUPR1 study𝕏
- 23 Dec 2024 Why KPIs Get Hacked and Miss the Real Problem𝕏
- 21 Dec 2024 Screenshot to Code turns mockups into ready-to-use code𝕏
- 21 Dec 2024 Three Tough Lessons From Building a SaaS Company𝕏
- 20 Dec 2024 Choosing SPA architecture for specialized apps𝕏
- 20 Dec 2024 Full server control with client flexibility in MPAs𝕏
- 18 Dec 2024 China's growth engines are buying government debt𝕏
- 18 Dec 2024 Waymo Robo Taxis in Tokyo Raise Europe Questions𝕏
- 17 Dec 2024 Trusting teams helps companies move faster and innovate𝕏
- 17 Dec 2024 Why flatter company structures help individual contributors thrive𝕏
- 17 Dec 2024 Why Flat Organizations Are More Productive𝕏
- 17 Dec 2024 Margin Debt Is Back at 2021 Levels𝕏
- 17 Dec 2024 European Accelerationism and the case for EU tech reform𝕏
- 16 Dec 2024 Offered $100K for Piano Companion and ChordIQ𝕏
- 15 Dec 2024 Founder CEOs Drive Higher Unicorn Valuations𝕏
- 11 Dec 2024 Why Trust Often Comes Before Cooperation𝕏
- 10 Dec 2024 Google's Willow quantum chip raises cryptography concerns𝕏
- 10 Dec 2024 Exercise intensity, adherence, and outcomes𝕏
- 10 Dec 2024 Exercise as a treatment for major depressive disorder𝕏
- 9 Dec 2024 Why Technicians Must Learn More Than Coding𝕏
- 9 Dec 2024 Your Product Isn’t That Special𝕏
- 7 Dec 2024 Your Product Isn’t Special, and That’s Okay
- 4 Dec 2024 Let Them Face the Consequences𝕏
- 3 Dec 2024 MicroStrategy’s Bitcoin Bet and the Antifragility Question𝕏
- 2 Dec 2024 Alibaba QwQ-32B Looks Impressive and Undervalued𝕏
- 30 Nov 2024 Yann LeCun on AGI and the limits of LLMs𝕏
- 25 Nov 2024 Why I think quitting too soon to build SaaS is a mistake𝕏
- 16 Nov 2024 UBI Looks Great on Paper but Gets Messy in Practice𝕏
- 13 Nov 2024 Efficiency and Fragility as Efficiency Approaches 100%𝕏
- 11 Nov 2024 Stuck? Try Walking It Off
- 8 Nov 2024 Latvia tax rates and paying yourself dividends𝕏
- 1 Nov 2024 Are We About to Enter Another AI Winter?
- 23 Oct 2024 How Wikipedia Was Fooled by a Decade-Long Hoax𝕏
- 23 Oct 2024 Zhemao hoaxes
- 22 Oct 2024 About
- 22 Oct 2024 Supporting builders instead of roasting code drama𝕏
- 22 Oct 2024 Father of 3 on productivity and time priorities𝕏
- 21 Oct 2024 AI Is Helping the Next Generation Achieve More𝕏
- 19 Oct 2024 Luck Is Preparation Meeting Opportunity𝕏
- 19 Oct 2024 Luck is overrated
- 18 Oct 2024 Why Musk’s X acquisition is bigger than a social network𝕏
- 17 Oct 2024 Today’s accomplishments were yesterday’s impossibilities
- 17 Oct 2024 Today’s impossible becomes tomorrow’s achievement𝕏
- 17 Oct 2024 When loophole chasing hurts real entrepreneurs𝕏
- 16 Oct 2024 Solving Big Problems While I Sleep𝕏
- 14 Oct 2024 Drowning in options
- 14 Oct 2024 Sohu AI chip promises huge speed for transformer models𝕏
- 14 Oct 2024 Why I Prefer Classics Over New Releases𝕏
- 11 Oct 2024 Ayn Rand on the government's limited role𝕏
- 10 Oct 2024 China’s crossroads on debt and growth𝕏
- 2 Oct 2024 Learning to love intensive training over time𝕏
- 30 Sept 2024 Arabica vs Robusta: Coffee Beans and Productivity𝕏
- 28 Sept 2024 Why hostel and hostile share the same Latin root𝕏
- 28 Sept 2024 The surprising shared root of hostel and hostile𝕏
- 28 Sept 2024 Why do “hostel” and “hostile” sound so similar?
- 27 Sept 2024 Why perfection is about taking away, not adding𝕏
- 25 Sept 2024 Why understanding code matters in an AI-driven world𝕏
- 24 Sept 2024 Following the blueprint and not overthinking𝕏
- 23 Sept 2024 Binaural Beats for Calm Thinking and Creative Focus𝕏
- 23 Sept 2024 PsyTrance Puts Me in Flow When I’m Coding𝕏
- 23 Sept 2024 How music genres fit different parts of my day𝕏
- 22 Sept 2024 First successful model-stealing attack on black-box AI models𝕏
- 21 Sept 2024 MVP vs PMF: Why They’re Not the Same𝕏
- 21 Sept 2024 How Different Music Genres Power My Life
- 19 Sept 2024 ChatGPT Bias Toward 42 Changes with Temperature and Language𝕏
- 18 Sept 2024 A book about productivity
- 18 Sept 2024 A tough lesson in failing fast from a social app build𝕏
- 18 Sept 2024 How Highlight, Laser, Reflect improved my productivity𝕏
- 17 Sept 2024 Famous bad predictions about technology𝕏
- 17 Sept 2024 A Coffee Snack Combo for Steady Midday Energy𝕏
- 16 Sept 2024 Five years of meditation and the benefits of mindfulness𝕏
- 12 Sept 2024 PMF and MVP